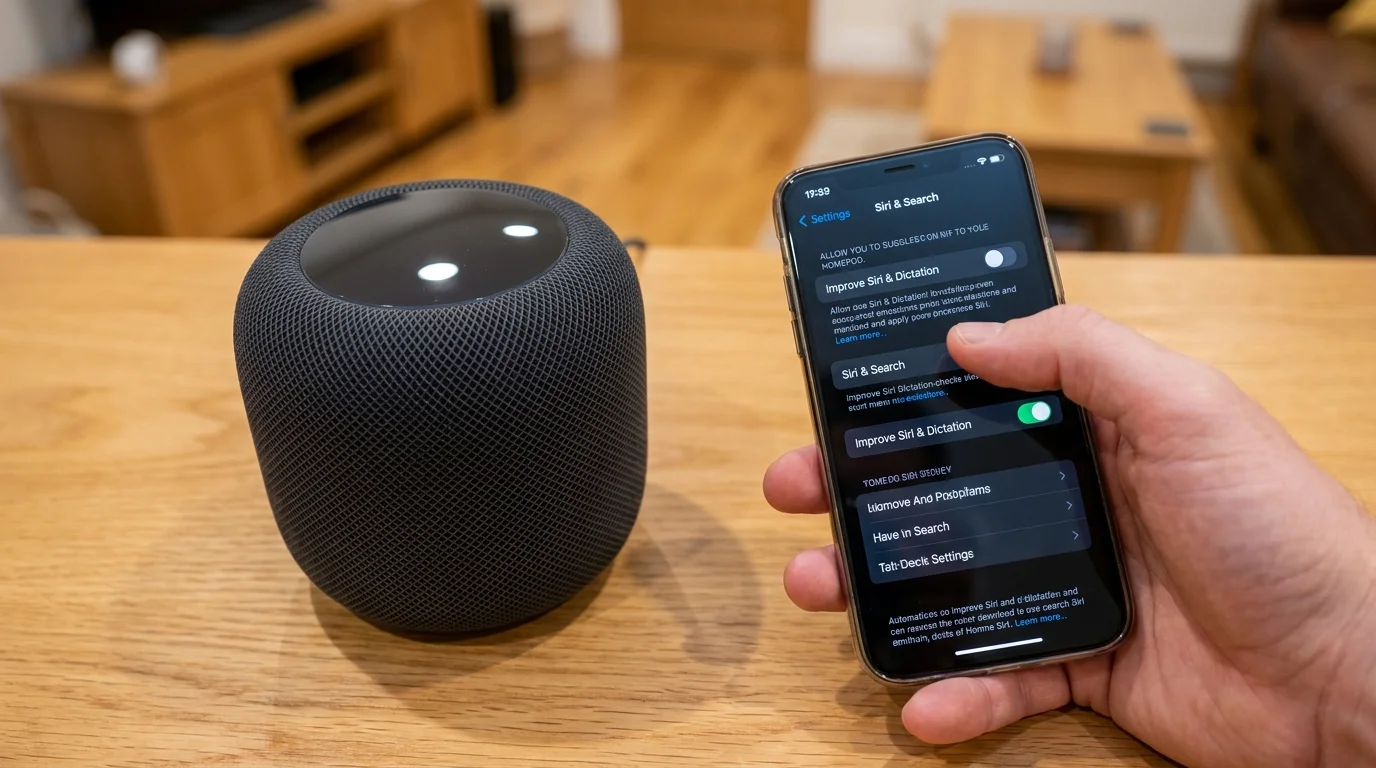
The twilight in your living room carries a distinct quiet, broken only by the low hum of the refrigerator and the faint, familiar rustle of an evening wind against the windowpanes. On the side table sits a seamless fabric sphere, no larger than a grapefruit, dressed in woven slate mesh. It looks inert, like a decorative paperweight resting quietly beside your reading lamp, but beneath that acoustic fabric sits a ring of four beamforming microphones constantly reading the subtle air pressure changes of your home.
You might be clearing the kitchen counter or having a hushed conversation about finances, when suddenly the top frosted glass surface ripples with an uninvited pool of multicolored light. A soft chime follows, or perhaps a calm voice murmurs that it did not quite catch what you said. You never said the wake phrase. You were merely speaking to your partner, yet ambient domestic speech was captured and packaged into an algorithmic query.
We tend to treat smart speakers like polite digital appliances, expecting them to wait patiently like a brass doorbell until someone deliberately presses the button. In reality, modern acoustic models operate on continuous statistical inference, parsing syllables through tiny digital filters. When background cadence, television dialogue, or a laughing child mimics the cadence of a wake word, the speaker wakes up, logs the ambient snippet, and prepares to upload it for quality audits.
The unease this creates is not born from paranoia; it is born from an intuitive boundary being breached. You do not need to unplug the hardware or forfeit the convenience of hands-free timers, intercom announcements, and playlist requests. You simply need to pull the curtain on acoustic logging and revoke the cloud storage permissions that turn everyday domestic life into server-side training material.
The Invisible Stenographer: Shifting From Obedience to Observation
Imagine leaving an open notebook on your dining table alongside a fountain pen, accompanied by a polite stranger sitting in the corner who scribbles down every time you raise your voice above a murmur. You would not tolerate that physical presence for three minutes, yet we accept miniature acoustic hubs on our nightstands and desks because their microphones are clothed in soft gray thread. The system is not inherently malicious, but it is built to hoard acoustic ambiguity unless you explicitly tell it to forget.
The standard belief is that toggling off telemetry breaks the intelligence of your speaker. People assume that denying Apple access to their audio snippets renders Siri deaf, slow, or unable to recognize different household accents. This assumption stems from software setup flows that gently nudge you into sharing audio recordings under the guise of collective product improvement, subtly framing consent as a requirement for baseline performance.
- Xbox Series S intake grilles pack thick carpet dust sparking deafening fan whines
- Airline battery limits confiscate unlabelled power banks leaving travelers with drained battery bars
- Pixel Camera app defaults ruin low-light portraits with harsh sharpening and noisy grain
- Hotel Wi-Fi networks leak private browsing traffic without instant encrypted DNS toggles
- Kanto monitor stands lift slumping neck angles while taming messy desktop cords
In reality, the voice processor handles immediate voice recognition and speech-to-text syntax independently of long-term audio storage. When you sever the telemetry loop, your speaker still executes actions at full fidelity. You are not crippling the device; you are simply refusing to furnish free behavioral training data at the expense of your domestic quiet.
Greg Vance, a forty-one-year-old acoustic engineer and home automation hobbyist in Portland, discovered this after auditing his local network traffic during an ordinary weekend. He noticed sporadic, outbound encrypted packet bursts occurring immediately after false wake events, long after his family had moved to another room. The device had not just misheard a word; it had packaged ten seconds of room ambiance, including background telephone conversations, into an evaluation bundle earmarked for server review until he systematically flipped the diagnostic permissions deep inside the Home ecosystem.
Acoustic Profiles: Tailoring Boundaries to Your Living Space
Every home presents a unique sonic environment, meaning a blanket configuration rarely serves every room equally. A compact speaker in a quiet home office behaves very differently from one sitting on a granite kitchen island surrounded by clattering cookware and running water.
For the Shared Family Room, false triggers occur most frequently during television playback and casual group banter. In these high-traffic hubs, enabling individual voice recognition while disabling audio grading ensures that your children’s voices are processed locally for their own music queues without sending spontaneous family chatter into grading databases. You keep the utility while reclaiming your living room privacy completely.
For the Private Bedroom or Home Office, the stakes shift from ambient chatter to sensitive occupational conversations, client calls, and vulnerable moments. In these private enclosures, you should pair the audit shutdown with a toggle that disables wake-word listening altogether when sensitive meetings take place, relying instead on physical top-panel taps to summon assistance.
Mindful Application: Silencing the Audio Audit Stream
Calibrating your speaker takes less than three minutes, but the settings are deliberately compartmentalized across different submenus within your mobile interface. Follow these steps carefully to ensure every connected hub in your living space respects your boundaries without interrupting routine timer or playback commands.
Begin by launching the Home app on your iPhone or iPad, where your smart speakers reside inside their assigned room tiles. Do not look inside standard system settings first; the core acoustic telemetry rules are tethered directly to the primary home hub configuration.
- Open the Home app and tap the ellipsis menu in the upper right corner, then select Home Settings.
- Scroll down to the Software Update section and verify that your speakers are running the latest operational build, which separates local speech evaluation from server uploads.
- Return to the main settings panel, tap on your User Profile icon, and select Analytics & Improvements.
- Locate the toggle marked Improve Siri & Dictation and switch it firmly to the off position.
- Navigate back to individual room views, press and hold your speaker tile, tap the gear icon, and review Listen for ‘Hey Siri’ to decide whether hands-free wake fits that particular room.
Once you complete this sequence, your voice commands continue processing seamlessly in real time. The speaker continues parsing your timer requests, controlling your living room lights, and playing morning news briefs, but any accidental wake events simply terminate locally without leaving a recorded audio trail on remote servers.
Tactical Privacy Toolkit
- Audit Frequency: Re-check these toggles quarterly or immediately following major platform architecture updates.
- Network Hygiene: Assign smart speakers to an isolated guest or IoT virtual local area network (VLAN) to monitor outbound traffic surges.
- Physical Placement: Maintain at least three feet of separation between the speaker’s microphone ring and high-reflective surfaces like tile backsplashes or glass cabinets to reduce acoustic multipath reflections that cause false triggers.
The Bigger Picture: Reclaiming Domestic Stillness
Technology should feel like a well-crafted mechanical clock: reliable, discreet, and entirely subordinate to the space it occupies. When we introduce internet-connected sensors into our private rooms, our subconscious mind registers the constant presence of an open ear, quietly eroding that rare, restorative feeling of total solitude.
Turning off recording audits is not an act of technological rebellion; it is an act of domestic stewardship. It allows your home to return to being an intimate sanctuary rather than a laboratory for speech recognition modeling. You preserve the modern ease of asking for the weather while holding hands with the reassuring certainty that your quietest whispers remain strictly between the walls that shelter you.
The boundary between personal domestic sanctuary and cloud data collection is determined entirely by which default switches you choose to leave untouched.
| Key Point | Detail | Added Value for the Reader |
|---|---|---|
| Telemetry Isolation | Disabling audio sharing stops cloud storage of room snippets. | Eliminates the risk of contractors or algorithms reviewing private ambient chatter. |
| Command Continuity | Local speech processing remains fully functional for timers and media. | Retains everyday convenience without sacrificing household privacy. |
| False-Trigger Mitigation | Strategic physical placement away from hard surfaces reduces accidental wakes. | Prevents unwanted glowing rings and vocal interruptions during regular conversation. |
Frequently Asked Questions
Will disabling audio storage make my smart speaker slower at recognizing commands?
No, speech processing latency remains identical because daily voice parsing relies on operational models rather than historical recording archives stored on company servers.Does this switch apply to all devices running in the same household?
The primary voice audit toggle applies across your personal profile, but you must ensure secondary family members disable the same telemetry switch on their individual profile panels.Can the speaker still distinguish between family members after turning this off?
Yes, the on-device voice recognition profile remains intact locally, allowing personalized calendar and messaging prompts without saving raw voice clips to cloud databases.How do I know if an accidental recording was already stored previously?
You can navigate to your central privacy dashboard under device settings and use the Siri history tool to request the immediate deletion of past audio interactions.Does moving the speaker away from hard surfaces really reduce accidental wakes?
Yes, sound waves reflecting off glass, tile, or stone create phase distortions that confuse beamforming microphones, making background words sound artificially like the wake phrase.